Trainium x Reactor Rolling Forcing
Using the Neuron Kernel Interface, a Reactor–AWS collaboration tackled the dynamic shapes, memory access patterns, and cache management that make real-time autoregressive diffusion hard—building techniques that generalize across models.
BioDiscovery-16x9.png
BioDiscovery-9x16.png
Three new papers from Amazon Bio Discovery address bottlenecks in AI-driven antibody engineering, from benchmarking binding predictors to experimentally validating de novo design.
CompressionModels-03-16x9.png
New research indicates that AI agents learn compressible models of data, which don’t have enough space to enable memorization.
Verus-16x9.gif
How the Verus "program verifier", which automatically checks code against a mathematical specification of its functionality, helps increase security assurance in software projects.
ARG10Year-Image02-16x9.png
Ten years after we founded the Automated Reasoning Group, mathematical logic has moved from academic research into production services that secure millions of customer workloads — demonstrating that systems can be provably correct, not just probably correct.
A kernel-centric path to real-time video generation on Trainium
Advancing AI for biology
Why don’t machine learning research agents overfit?
Developing provably correct Rust code with Verus
A decade of mathematical certainty

Customer-obsessed science

publications-lead-image.png

Research areas

From the blog

View all
Technical deep-dives and perspectives from our scientists.
View all

Featured news

The Build on Trainium program is a $110 million credit initiative supporting AI research at 30 universities including Stanford, UC Berkeley, UIUC, UCLA, CMU, and MIT, with a focus on Responsible AI.
The Antibody Developability Benchmark is powered by one of the most diverse antibody datasets in public literature, enabling transparent performance evaluation for AI-guided antibody design.
Challenge pushes teams to demonstrate measurable gains in secure-coding performance while building AI agents that advance real-world utility and reliability at scale.
Initiative will fund over 100 doctoral students researching machine learning, computer vision, and natural-language processing at nine universities.

Publications

View all View all
  • Sijia Wang, Alexander Li, Henry Zhu, Sheng Zhang, Chung-Wei Hang, Pramuditha Perera, JIE MA, William Wang, Zhiguo Wang, Vittorio Castelli, Bing Xiang, Patrick Ng
    ACL Findings 2023
    2023
    Entities can be expressed in diverse formats, such as texts, images, or column names and cell values in tables. While existing entity linking (EL) models work well on per modality configuration, such as text-only EL, visual grounding, or schema linking, it is more challenging to design a unified model for diverse modality configurations. To bring various modality configurations together, we constructed
  • Hilaf Hasson, Danielle Maddix Robinson, Yuyang (Bernie) Wang, Gaurav Gupta, Youngsuk Park
    ICML 2023
    2023
    Ensembling is among the most popular tools in machine learning (ML) due to its effectiveness in minimizing variance and thus improving generalization. Most ensembling methods for black-box base learners fall under the umbrella of “stacked generalization,” namely training an ML algorithm that takes the inferences from the base learners as input. While stacking has been widely applied in practice, its theoretical
  • Simiao Zuo, Qingyu Yin, Haoming Jiang, Shaohui Xi, Bing Yin, Chao Zhang, Tuo Zhao
    ACL 2023
    2023
    E-commerce queries are often short and ambiguous. Consequently, query understanding often uses query rewriting to disambiguate user input queries. While using e-commerce search tools, users tend to enter multiple searches, which we call context, before purchasing. These history searches contain contextual insights about users’ true shopping intents. Therefore, modeling such contextual information is critical
  • ACL Findings 2023
    2023
    We propose CHRT (Control Hidden Representation Transformation) — a controlled language generation framework that steers large language models to generate text pertaining to certain attributes (such as toxicity). CHRT gains attribute control by modifying the hidden representation of the base model through learned transformations. We employ a contrastive-learning framework to learn these transformations that
  • Nihal Jain, Dejiao Zhang, Wasi Ahmad, Zijian Wang, Feng Nan, Xiaopeng LI, Ming Tan, Ramesh Nallapati, Baishakhi Ray, Parminder Bhatia, Xiaofei Ma, Bing Xiang
    ACL 2023
    2023
    Despite exciting progress in causal language models, the expressiveness of their representations is largely limited due to poor discrimination ability. To remedy this issue, we present CONTRACLM, a novel contrastive learning framework at both the token-level and the sequence-level. We assess CONTRACLM on a variety of downstream tasks. We show that CONTRACLM enhances the discrimination of representations

Collaborations

View all
Whether you're a faculty member or student, there are number of ways you can engage with Amazon.
View all
Russ Tedrake (Massachusetts Institute of Technology).JPG
Gretchen Ertl
The program offers unrestricted funds and other resources to support research at academic institutions and non-profit organizations in areas that align with our mission.
A global university competition to drive secure innovation in generative AI technology, which focuses on responsible AI and large language model coding security.
Tübingen research center
Credit: Wolfram Scheible
We partner with particular academic organizations across the world for deep and sustained collaborations in multiple research areas of mutual interest.
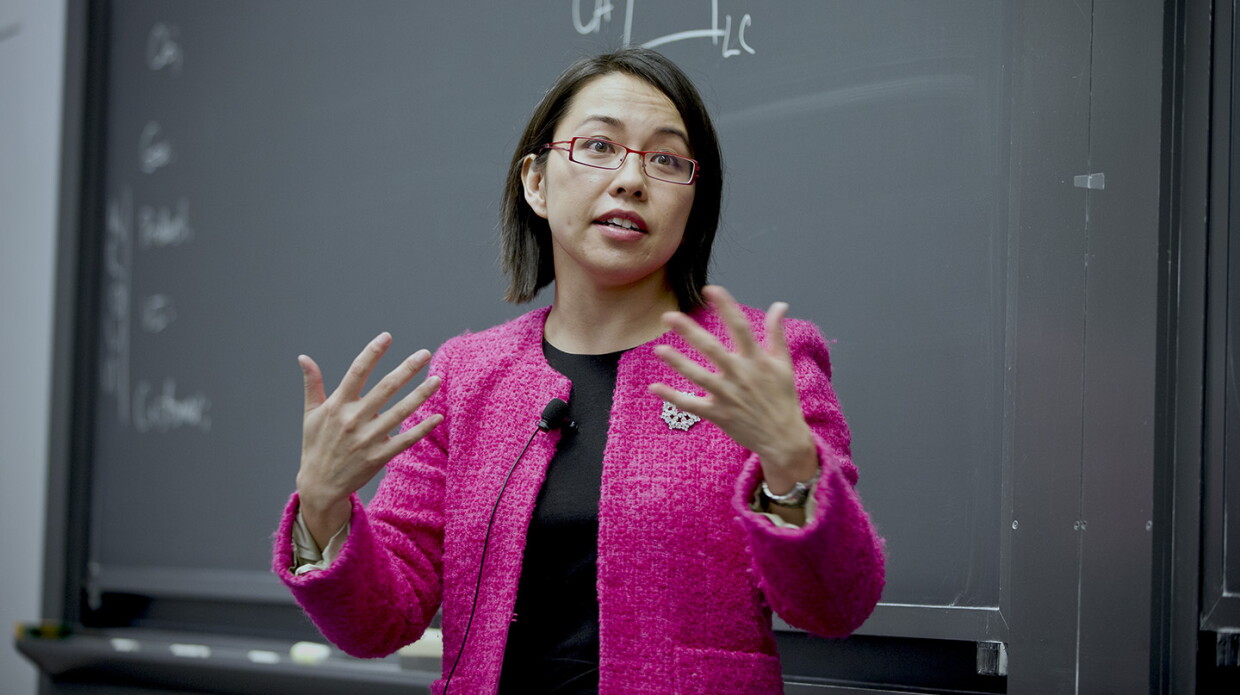
Pai-Ling Yin, senior manager of research science, is seen speaking to a classroom, there is a chalkboard behind her and she is gesturing with her hands.
Courtesy of Pai-Ling Yin
We hire world-class academics to work on large-scale technical challenges, while they continue to teach and conduct research at their universities.
IN, TS, Hyderabad
Are you passionate about solving complex problems with machine learning and scientific rigor? As an Applied Scientist I at Amazon, you will translate real-world business challenges into well-defined scientific problems and build solutions that directly benefit customers. You will work alongside experienced scientists and engineers, applying your expertise in areas such as natural language processing, computer vision, or robotics to design experiments, develop models, and deliver production-ready code. This is a role where your curiosity and technical depth will drive meaningful impact from day one. Key job responsibilities - Design, develop, and implement machine learning models and algorithms to solve well-defined business problems, mapping business goals and metrics to scientific approaches and evaluation criteria. - Write secure, stable, testable, and maintainable production code, applying state-of-the-art data structures and algorithms while following software development best practices at a high quality bar. - Conduct rigorous experiments to evaluate model performance, benchmark results against current research, and iterate on solutions to improve accuracy and customer outcomes. - Collaborate with team members to scope technical approaches, communicate findings through internal research reports, and contribute to peer-reviewed publications when aligned with business needs. - Stay current with research trends in your area of expertise, champion the adoption of recent scientific advancements, and help onboard and mentor scientist interns. A day in the life You might start your morning reviewing experiment results from a model you trained, analyzing performance metrics and identifying areas for improvement. After a design discussion with your team, you refine your approach and push updated code for review. In the afternoon, you read a recent research paper recommended by a senior scientist, exploring whether a new technique could improve your current solution. You wrap up by documenting your methodology so teammates can understand and build on your work. About the team Our team is focused on applying scientific methods and machine learning to solve problems that matter to Amazon's customers. We value rigorous experimentation, clear communication, and a collaborative environment where scientists at every stage of their career can grow. We are building toward solutions that push the boundaries of what is possible, and we are looking for curious, thoughtful scientists who want to contribute to that mission and learn alongside a supportive group of peers.
IN, TS, Hyderabad
Welcome to the Worldwide Returns & ReCommerce team (WWR&R) at Amazon.com. WWR&R is an agile, innovative organization dedicated to ‘making zero happen’ to benefit our customers, our company, and the environment. Our goal is to achieve the three zeroes: zero cost of returns, zero waste, and zero defects. We do this by developing products and driving truly innovative operational excellence to help customers keep what they buy, recover returned and damaged product value, keep thousands of tons of waste from landfills, and create the best customer returns experience in the world. We have an eye to the future – we create long-term value at Amazon by focusing not just on the bottom line, but on the planet. We are building the most sustainable re-use channel we can by driving multiple aspects of the Circular Economy for Amazon – Returns & ReCommerce. Amazon WWR&R is comprised of business, product, operational, program, software engineering and data teams that manage the life of a returned or damaged product from a customer to the warehouse and on to its next best use. Our work is broad and deep: we train machine learning models to automate routing and find signals to optimize re-use; we invent new channels to give products a second life; we develop highly respected product support to help customers love what they buy; we pilot smarter product evaluations; we work from the customer backward to find ways to make the return experience remarkably delightful and easy; and we do it all while scrutinizing our business with laser focus. You will help create everything from customer-facing and vendor-facing websites to the internal software and tools behind the reverse-logistics process. You can develop scalable, high-availability solutions to solve complex and broad business problems. We are a group that has fun at work while driving incredible customer, business, and environmental impact. We are backed by a strong leadership group dedicated to operational excellence that empowers a reasonable work-life balance. As an established, experienced team, we offer the scope and support needed for substantial career growth. Amazon is earth’s most customer-centric company and through WWR&R, the earth is our customer too. Come join us and innovate with the Amazon Worldwide Returns & ReCommerce team! Key job responsibilities * Design, develop, and evaluate highly innovative models for Natural Language Programming (NLP), Large Language Model (LLM), or Large Computer Vision Models. * Use SQL to query and analyze the data. * Use Python, Jupyter notebook, and Pytorch to train/test/deploy ML models. * Use machine learning and analytical techniques to create scalable solutions for business problems. * Research and implement novel machine learning and statistical approaches. * Mentor interns. * Work closely with data & software engineering teams to build model implementations and integrate successful models and algorithms in production systems at very large scale. About the team When a customer returns a package to Amazon, the request and package will be passed through our WWRR machine learning (ML) systems so that we could improve the customer experience, identify return root cause, optimize re-use, and evaluate the returned package. Our problems touch multiple modalities spanning from: textual, categorical, image, to speech data. We operate at large scale and rely on state-of-the-art modeling techniques to power our ML models: XGBoost, BERT, Vision Transformers, Large Language Models.
US, MA, Boston
We are looking for researchers who aim to build super-intelligent AI systems that leverage proof assistants to guide learning and reasoning. Our neuro-symbolic AI technology is applied across a wide range of science and engineering domains within Amazon, and you will join the team at the forefront of this research. As an Applied Scientist, you will play a pivotal role in shaping the definition, vision, and development of product features from beginning to end. You will: - Define and implement new neuro-symbolic applications that employ scalable and efficient approaches to solve complex problems. - Work in an agile, startup-like development environment, where you are always working on the most important stuff. - Deliver high-quality scientific artifacts. About the team We work closely with academia. Our team includes an Amazon Scholar in mathematics, and we maintain active research collaborations with faculty at leading CS departments (MIT, Berkeley, CMU).
IN, KA, Bengaluru
RBS (Retail Business Services) Tech team works towards enhancing the customer experience (CX) and their trust in product data by providing technologies to find and fix Amazon CX defects at scale. Our platforms help in improving the CX in all phases of customer journey, including selection, discoverability & fulfilment, buying experience and post-buying experience (product quality and customer returns). The team also develops GenAI platforms for automation of Amazon Stores Operations. As a Sciences team in RBS Tech, we focus on foundational ML research and develop scalable state-of-the-art ML solutions to solve the problems covering customer experience (CX) and Selling partner experience (SPX). We work to solve problems related to multi-modal understanding (text and images), task automation through multi-modal LLM Agents, supervised and unsupervised techniques, multi-task learning, multi-label classification, aspect and topic extraction for Customer Anecdote Mining, image and text similarity and retrieval using NLP and Computer Vision for product groupings and identifying duplicate listings in product search results. Key job responsibilities As an Applied Scientist, you will be responsible to design and deploy scalable GenAI, NLP and Computer Vision solutions that will impact the content visible to millions of customer and solve key customer experience issues. You will develop novel LLM, deep learning and statistical techniques for task automation, text processing, image processing, pattern recognition, and anomaly detection problems. You will define the research and experiments strategy with an iterative execution approach to develop AI/ML models and progressively improve the results over time. You will partner with business and engineering teams to identify and solve large and significantly complex problems that require scientific innovation. You will help the team leverage your expertise, by coaching and mentoring. You will contribute to the professional development of colleagues, improving their technical knowledge and the engineering practices. You will independently as well as guide team to file for patents and/or publish research work where opportunities arise. The RBS org deals with problems that are directly related to the selling partners and end customers and the ML team drives resolution to organization level problems. Therefore, the Applied Scientist role will impact the large product strategy, identifies new business opportunities and provides strategic direction which is very exciting.
US, NJ, Newark
At Audible, we believe stories have the power to transform lives. It’s why we work with some of the world’s leading creators to produce and share audio storytelling with our millions of global listeners. We are dreamers and inventors who come from a wide range of backgrounds and experiences to empower and inspire each other. Imagine your future with us. ABOUT THIS ROLE We are seeking a data scientist builder to join the Audible economics team. Our group of economists, data scientists, and analysts tackles a wide range of questions, including pricing, experimentation science, data-driven product strategy/optimizations, internal productivity/incentives, audience science, and impact/ROI measurement. The ideal candidate will enjoy wearing many hats, possess an economist's mindset and a strong ability to effectively translate business questions into tractable quantitative frameworks, and excel at leveraging AI to build and scale robust, interpretable, and production-ready models/systems/tools. We're looking for someone who automates the repetitive, builds tools that force-multiply the team's output/influence, and treats AI as a core part of their workflow - not a side project. If you are passionate about leveraging data to shape the future of digital media, we encourage you to apply and be a part of our dynamic team. As a Data Scientist, you will... - Collaborate with economists, analysts, and other data scientists to build and scale econometric/ML models and quantitative tools - owning end-to-end scoping, data pipelining, feature engineering, model development/refinement, production-grade deployment, impact measurement, and adoption - Research and evaluate emerging tools and techniques (AI-driven and otherwise), and identify novel data sources to leverage in quantitative work – both from within Audible/Amazon and from 3P sources - Collaborate closely with Product, Content, and Marketing partners to drive broad impact and ensure that solutions are integrated into cross-functional workflows and executive decision-making - Represent the team in a range of settings - from reviews with senior Amazon scientists to reviews with senior Audible/Amazon business leaders - Mentor junior scientists and raise the bar for a new generation of scalable, AI-enabled science/analytical work, both within Audible and across the broader Amazon community ABOUT AUDIBLE Audible is the leading producer and provider of audio storytelling. We spark listeners’ imaginations, offering immersive, cinematic experiences full of inspiration and insight to enrich our customers daily lives. We are a global company with an entrepreneurial spirit. We are dreamers and inventors who are passionate about the positive impact Audible can make for our customers and our neighbors. This spirit courses throughout Audible, supporting a culture of creativity and inclusion built on our People Principles and our mission to build more equitable communities in the cities we call home. Key job responsibilities
IN, KA, Bengaluru
Are you passionate about giving customers the richest, most inspiring experience in their shopping journey? Do you like to dive deep to understand how customer-centric solutions drive measurable results? Do you enjoy working closely with the business and software engineers to design rigorous experiments, build the data infrastructure behind them, and translate results into decisions? You are in the right place! Come join our Prime & Marketing Analytics and Science (PRIMAS) team, where your work will directly impact millions of customers. The EU Marketing & Prime organization is looking for a Data Scientist to join the PRIMAS team. This role sits at the intersection of applied statistics and large-scale analytics — you'll design experiments and causal models, and also own the data pipelines, metrics, and reporting infrastructure that make those results usable across the business. The PRIMAS team provides a comprehensive understanding of customer segments, affinities, and lifetime value. We use data science tools and advanced statistical techniques to study customer purchase and engagement behaviors, and generate actionable insights on where, when, and how we deliver products and programs to customers. We help increase customer engagement, sales, and marketing efficiency, and our systems are built entirely in-house on automated large-scale analytics infrastructure. You will design, launch, and measure experiments across marketing channels (SEM/SEO, Affiliates, Display, Social, Mobile, Email, Onsite, etc.), engagement products, and customer segments. You will improve our understanding of customer behavior, run rigorous power and minimum detectable effect (MDE) analyses to size experiments correctly, and build the causal and conversion models that value and target our marketing — then build the pipelines and dashboards that keep those signals flowing reliably to stakeholders and downstream systems. You will work at the forefront of consumer analytics, tackling some of the hardest measurement problems in the industry alongside strong scientists, statisticians, and software engineers. Key job responsibilities 1. Design and implement scalable, statistically rigorous experiments (A/B, geo, holdout, quasi-experiments) to measure marketing incrementality across channels. 2. Perform power analysis and minimum detectable effect (MDE) calculations to determine experiment sample sizes, durations, and design trade-offs before launch. 3. Build causal and treatment-effect models that produce conversion and valuation signals consumed by downstream bidding and budgeting systems. 4. Building the ETL, metric definitions, and datasets that make results scalable, extensible, and repeatable rather than one-off analyses. 5. Develop measurement frameworks that quantify the true, platform-independent contribution of marketing over time, and build the dashboards and reporting that keep those metrics visible to the business. 6. Apply statistical, mathematical, and machine learning techniques to solve ambiguous business problems where the right approach isn't obvious. 7. Analyze experiment results for validity — inspecting distributions, checking for sample ratio mismatch, exploring covariate balance, and tracking down the source of anomalies. 8. Communicate experiment design, results, and trade-offs clearly to business and leadership audiences, including inputs into business reviews, and influence decisions and technical direction across teams. 9. Establish scalable, repeatable processes and best practices for experiment design, data modeling, and analysis.
IN, KA, Bengaluru
Amazon Advertising Trust is on a mission to redefine how trust is enforced at internet scale, and we are looking for exceptional scientists to help lead the way. We are building systems that reason about advertising content the way a trained human would, at a industry leading volume and speed, and that keep working when the rules change underneath them. At Ads Trust Science we leverage machine learning, generative AI, and large-scale retrieval to solve some of the most complex decision problems for ads worldwide. Every ad shown across Amazon's owned-and-operated properties and third-party networks, in every format and every global marketplace, depends on decisions our systems make. We are just getting started. As a Senior Applied Scientist you will be at the forefront of this work. You will own science problems end to end, bridging the gap between research and production impact. You will not be handed a specification. You will be given a customer problem, a system that partly solves it, and the latitude to decide what to build next. This is a unique opportunity to work at the intersection of multimodal understanding, large language models, and large-scale retrieval, on a problem where the science is genuinely unsettled. You will work alongside scientists whose models run in front of hundreds of millions of customers, at a scale that changes which approaches are even possible. A day in the life - Ship a model into production, then find and document where it fails once real traffic reaches it. - Drive the technical discussion, inside your team and with partner teams, on how to close that gap. - Bring a fresh angle to a problem that is not yours and help a peer get further than they would have alone, building trust across the team in the process. - Mentor while staying hands-on. At this level the design and the code are both yours. About the team Ads Trust Science is a group of scientists who would rather change what the team measures than optimise the wrong number. We value curiosity, rigour, and a bias for action. We expect people to disagree with evidence, to say clearly what did not work, and to iterate quickly toward the solutions that matter.
US, CA, San Francisco
Are you a brilliant mind seeking to push the boundaries of what's possible with intelligent robotics? Join our elite team of researchers and engineers - led by Pieter Abeel, Rocky Duan, and Peter Chen - at the forefront of applied science, where we're harnessing the latest advancements in large language models (LLMs) and generative AI to reshape the world of robotics and unlock new realms of innovation. As an Applied Science Intern, you'll have the unique opportunity to work alongside world-renowned experts, gaining invaluable hands-on experience with cutting-edge robotics technologies. You'll dive deep into exciting research projects at the intersection of AI and robotics. This internship is not just about executing tasks – it's about being a driving force behind groundbreaking discoveries. You'll collaborate with cross-functional teams, leveraging your expertise in areas such as deep learning, reinforcement learning, computer vision, and motion planning to tackle real-world problems and deliver impactful solutions. Throughout your journey, you'll have access to unparalleled resources, including state-of-the-art computing infrastructure, cutting-edge research papers, and mentorship from industry luminaries. This immersive experience will not only sharpen your technical skills but also cultivate your ability to think critically, communicate effectively, and thrive in a fast-paced, innovative environment where bold ideas are celebrated. Join us at the forefront of applied robotics and AI, where your contributions will shape the future of intelligent systems and propel humanity forward. Seize this extraordinary opportunity to learn, grow, and leave an indelible mark on the world of technology. Amazon has positions available in San Francisco, CA. The ideal candidate should possess: - Strong background in machine learning, deep learning, and/or robotics - Publication record at science conferences such as NeurIPS, CVPR, ICRA, RSS, CoRL, and ICLR. - Experience in areas such as multimodal LLMs, world models, image/video tokenization, real2Sim/Sim2real transfer, bimanual manipulation, open-vocabulary panoptic scene understanding, scaling up multi-modal LLMs, and end-to-end vision-language-action models. - Proficiency in Python, Experience with PyTorch or JAX - Excellent problem-solving skills, attention to detail, and the ability to work collaboratively in a team Apply now and embark on an extraordinary journey of discovery and innovation! Key job responsibilities - Develop novel, scalable algorithms and modeling techniques that advance the state-of-the-art in areas at the intersection of LLMs and generative AI for robotics - Tackle challenging, groundbreaking research problems on production-scale data, with a focus on robotic perception, manipulation, and control - Collaborate with cross-functional teams to solve complex problems, and to communicate research findings clearly, leveraging your expertise in areas such as deep learning, reinforcement learning, computer vision, and motion planning - Demonstrate the ability to work independently, thrive in a fast-paced, ever-changing environment, and communicate effectively with diverse stakeholders Leverage AI-powered tools where applicable to accelerate research, experimentation, and prototyping. Critically review and validate outputs from AI tools and automated systems.
US, WA, Seattle
Unleash Your Potential as an AI Trailblazer At Amazon, we're on a mission to revolutionize the way people discover and access information. Our Applied Science team is at the forefront of this endeavor, pushing the boundaries of recommender systems and information retrieval. We're seeking brilliant minds to join us as interns and contribute to the development of cutting-edge AI solutions that will shape the future of personalized experiences. As an Applied Science Intern focused on Recommender Systems and Information Retrieval in Machine Learning, you'll have the opportunity to work alongside renowned scientists and engineers, tackling complex challenges in areas such as deep learning, natural language processing, and large-scale distributed systems. Your contributions will directly impact the products and services used by millions of Amazon customers worldwide. Imagine a role where you immerse yourself in groundbreaking research, exploring novel machine learning models for product recommendations, personalized search, and information retrieval tasks. You'll leverage natural language processing and information retrieval techniques to unlock insights from vast repositories of unstructured data, fueling the next generation of AI applications. Throughout your journey, you'll have access to unparalleled resources, including state-of-the-art computing infrastructure, cutting-edge research papers, and mentorship from industry luminaries. This immersive experience will not only sharpen your technical skills but also cultivate your ability to think critically, communicate effectively, and thrive in a fast-paced, innovative environment where bold ideas are celebrated. Join us at the forefront of applied science, where your contributions will shape the future of AI and propel humanity forward. Seize this extraordinary opportunity to learn, grow, and leave an indelible mark on the world of technology. Must be eligible and available for a full-time (40h / week) 12 week internship between May 2026 and September 2026 Amazon has positions available for Machine Learning Applied Science Internships in, but not limited to Arlington, VA; Bellevue, WA; Boston, MA; New York, NY; Palo Alto, CA; San Diego, CA; Santa Clara, CA; Seattle, WA. Key job responsibilities We are particularly interested in candidates with expertise in: Knowledge Graphs and Extraction, Programming/Scripting Languages, Time Series, Machine Learning, Natural Language Processing, Deep Learning,Neural Networks/GNNs, Large Language Models, Data Structures and Algorithms, Graph Modeling, Collaborative Filtering, Learning to Rank, Recommender Systems In this role, you'll collaborate with brilliant minds to develop innovative frameworks and tools that streamline the lifecycle of machine learning assets, from data to deployed models in areas at the intersection of Knowledge Management within Machine Learning. You will conduct groundbreaking research into emerging best practices and innovations in the field of ML operations, knowledge engineering, and information management, proposing novel approaches that could further enhance Amazon's machine learning capabilities. The ideal candidate should possess the ability to work collaboratively with diverse groups and cross-functional teams to solve complex problems, and to communicate research findings clearly. A successful candidate will be a self-starter, comfortable with ambiguity, with strong attention to detail and the ability to thrive in a fast-paced, ever-changing environment. Leverage AI-powered tools where applicable to accelerate research, experimentation, and prototyping. Critically review and validate outputs from AI tools and automated systems. A day in the life - Design, implement, and experimentally evaluate new recommendation and search algorithms using large-scale datasets - Develop scalable data processing pipelines to ingest, clean, and featurize diverse data sources for model training - Conduct research into the latest advancements in recommender systems, information retrieval, and related machine learning domains - Collaborate with cross-functional teams to integrate your innovative solutions into production systems, impacting millions of Amazon customers worldwide - Communicate your findings through captivating presentations, technical documentation, and potential publications, sharing your knowledge with the global AI community
US, WA, Seattle
Unlock the Future with Amazon Science! Calling all visionary minds passionate about the transformative power of machine learning! Amazon is seeking boundary-pushing graduate student scientists who can turn revolutionary theory into awe-inspiring reality. Join our team of visionary scientists and embark on a journey to revolutionize the field by harnessing the power of cutting-edge techniques in bayesian optimization, time series, multi-armed bandits and more. At Amazon, we don't just talk about innovation – we live and breathe it. You'll conducting research into the theory and application of deep reinforcement learning. You will work on some of the most difficult problems in the industry with some of the best product managers, scientists, and software engineers in the industry. You will propose and deploy solutions that will likely draw from a range of scientific areas such as supervised, semi-supervised and unsupervised learning, reinforcement learning, advanced statistical modeling, and graph models. Throughout your journey, you'll have access to unparalleled resources, including state-of-the-art computing infrastructure, cutting-edge research papers, and mentorship from industry luminaries. This immersive experience will not only sharpen your technical skills but also cultivate your ability to think critically, communicate effectively, and thrive in a fast-paced, innovative environment where bold ideas are celebrated. Join us at the forefront of applied science, where your contributions will shape the future of AI and propel humanity forward. Seize this extraordinary opportunity to learn, grow, and leave an indelible mark on the world of technology. Amazon has positions available for Machine Learning Applied Science Internships in, but not limited to Arlington, VA; Bellevue, WA; Boston, MA; New York, NY; Palo Alto, CA; San Diego, CA; Santa Clara, CA; Seattle, WA. Key job responsibilities We are particularly interested in candidates with expertise in: Optimization, Programming/Scripting Languages, Statistics, Reinforcement Learning, Causal Inference, Large Language Models, Time Series, Graph Modeling, Supervised/Unsupervised Learning, Deep Learning, Predictive Modeling In this role, you will work alongside global experts to develop and implement novel, scalable algorithms and modeling techniques that advance the state-of-the-art in areas at the intersection of Reinforcement Learning and Optimization within Machine Learning. You will tackle challenging, groundbreaking research problems on production-scale data, with a focus on developing novel RL algorithms and applying them to complex, real-world challenges. The ideal candidate should possess the ability to work collaboratively with diverse groups and cross-functional teams to solve complex business problems, and to communicate research findings clearly. A successful candidate will be a self-starter, comfortable with ambiguity, with strong attention to detail and the ability to thrive in a fast-paced, ever-changing environment. Leverage AI-powered tools where applicable to accelerate research, experimentation, and prototyping. Critically review and validate outputs from AI tools and automated systems. A day in the life - Develop scalable, efficient, automated processes for large scale data analyses, model development, model validation and model implementation. - Design, development and evaluation of highly innovative ML models for solving complex business problems. - Research and apply the latest ML techniques and best practices from both academia and industry. - Think about customers and how to improve the customer delivery experience. - Use and analytical techniques to create scalable solutions for business problems.
