CompressionModels-03-16x9.png
The more your listener already knows, the shorter the message you need to send. An expert ML engineer needs only a few sentences; a newcomer needs the whole manual.

Why don’t machine learning research agents overfit?

New research indicates that AI agents learn compressible models of data, which don’t have enough space to enable memorization.

Key takeaways
  • ML models don't overfit benchmarks, even after many rounds of iterative improvement. This contradicts textbook predictions that repeatedly evaluating against the same held-out data should lead to overfitting.
  • Experiments with ML research agents indicate that successful strategies are highly compressible. When a successful agent's strategy is squeezed through an information bottleneck (as few as 16 tokens), a fresh agent with no memory can reproduce the original agent's performance, meaning the strategy captured real structure, not memorized data.
  • Compression provides both an explanation and a diagnostic tool. Strategies that genuinely overfit fail the compression test: their validation-specific gains vanish when passed through the bottleneck.
  • LLMs are powerful compression decoders. Because they carry vast world knowledge, they can reconstruct full ML pipelines from terse, expert-shorthand prompts, which is a concrete way of understanding why they're so capable.
Was this answer helpful?

Machine learning, at its core, is about generalization, not memorization. You hand your learning algorithm a pile of training examples and use them to fit a model. But the goal is not to perform well on the training examples — that's easy, you could just memorize the answers. The goal is to perform well on new examples that you have never before seen. If a model does well on the data it was trained on but poorly on fresh data, it hasn’t actually learned anything; you have only fooled yourself into thinking it has. This failure mode has a name: overfitting.

Anyone who has taken an introductory statistics or machine learning class knows the standard defense. You hold out some of your data and refuse to train on it. In practice, this held-out data plays two roles. A validation set is one you consult repeatedly while building the model — to compare candidates, tune hyperparameters, and decide what to try next. A final test set (or holdout) is meant to be touched only once, at the very end: because the training procedure never saw it, strong performance there is a correct proxy for the new examples you will encounter in the wild.

Machine learning, at its core, is about generalization, not memorization

The “holdout” condition is crucial, though. The correct-proxy guarantee holds if the held-out set stays genuinely unseen. If you check your performance on it, tweak your training procedure in response, recheck, and iterate, chasing better and better numbers, that set is no longer unseen; it has become part of your training procedure. Do this enough times, and you can overfit it just as you might have overfit the training set, and you have lost your proxy for unseen data. This is true of any held-out set you reuse this way, including a validation set, which is reused by design.

A puzzle at the heart of machine learning

Real machine learning research looks exactly like the iterative improvement loop we just described. Everyone gauges performance using a handful of benchmark datasets that go unrevised for years. The research community repeats an enormous, distributed loop: evaluate a model on the benchmark, revise the training procedure, re-evaluate, publish, and let the next group eke out a little more improvement.

This is precisely the kind of hill-climbing against a held-out set that, by the textbook account, ought to produce rampant overfitting. By now, the leaderboards should be saturated with models that look great on the benchmark and mediocre everywhere else.

And yet that is not what happens. Studies that build entirely fresh test sets for old, heavily reused benchmarks have found that improvements largely transfer: on the new data, models demonstrate the same gains they did on the old benchmark. Benchmark-driven machine learning, against the textbook's prediction, has produced rapid and largely real progress. Why?

There is no shortage of hypotheses, but they have been hard to test empirically, because the "subject" of the experiment is the entire human research community. You cannot reset a field, wipe its memory, and rerun the last decade under controlled conditions.

But we can do something similar. We now have capable, LLM-based research agents that can autonomously run the same machine-learning optimization loops that human communities run. They engage in the same benchmark hill-climbing — and, intriguingly, they too seem not to overfit. The difference is that an agent, unlike a research community, is something you can reset. You can clear its memory, control exactly what information it sees, and run the experiment again. In a recent paper, "What fits (into few tokens) doesn't overfit: Compression and generalization in ML research agents", we do exactly that — and in the process offer a concrete explanation for the long-standing mystery.

Occam's razor, made precise

The explanation begins with a very old idea. Occam's razor says that among hypotheses that explain the data equally well, the simpler one is more likely to be correct. It turns out this intuition has a precise mathematical form, and it is what underlies the whole story.

Suppose you can describe your hypothesis — your model, your strategy — in a small number of bits, far fewer than it would take to memorize the training data. If that compact hypothesis performs very well on the training data, it must also perform well on new data.

Occam's razor, formalized: among hypotheses that explain the data equally well, the simpler one — describable in fewer bits — is more likely to generalize to new examples.

The reasoning runs through a counting argument. There simply are not very many short descriptions, because there are not very many short strings. The fewer candidate hypotheses there are, the less likely it is that any one of them fooled you on the training set by luck — even though you used the training set to guide your search.

Another way to get the intuition: if your compressed description is too small to secretly record the training data, then when it performs well on the training data, it cannot be because it memorized the answers — it didn't have space to do that. It must be because it captured something true about the data's structure. Short descriptions cannot cheat because there isn't room.

Here is an attractive hypothesis: successful machine learning strategies are highly compressible. A researcher might stare at thousands of benchmark scores over the course of a project, but the strategy that ultimately survives is usually a short list of familiar choices — an architecture family, an optimizer, a learning-rate schedule, a data-handling recipe, a regularization scheme. If that final recipe can be communicated in just a few bits, then the model's true dependence on the benchmark is far smaller than the long, winding transcript of experiments would suggest. The hill-climbing was extensive, but the thing that came out the other end was — or could have been — tiny.

Compression, intelligence, and the power of a knowledgeable listener

Imagine trying to explain a specific machine learning pipeline to a bright high-school student, in enough detail that they could actually reproduce it. It would be a long, laborious conversation. You would have to explain what gradient descent is, what a neural network is, what PyTorch or JAX or TensorFlow does, what a learning rate is, and on and on. Almost none of that is specific to your problem; it is general background about how machine learning works.

Now imagine explaining the same pipeline to an expert ML engineer. The conversation now collapses to a few sentences. You skip everything that counts as common knowledge and communicate only what is genuinely specific to this problem: the architecture choice, the batch size, the optimizer, a couple of hyperparameters. The more your listener already knows about the world, the shorter the message you need to send — and the more aggressively you can compress. None of this "world knowledge" counts against you in the Occam's-razor argument, because you could have written all of that down without having looked at the training set.

This is where large language models enter the picture. Modern LLMs carry an enormous amount of world knowledge. They know how ML tooling works; they know the standard optimization algorithms; they know the conventional hyperparameter choices and the common defaults. If a detail is left unspecified, they can fill in a plausible value. That makes them extraordinarily good compression decoders: hand an LLM a terse, expert-to-expert message, and it can unpack it into a full, working procedure. If you think about it, this is exactly why they are so powerful.

The experiment: Squeezing a strategy through a bottleneck

This suggests a clean experiment. Have an ML research agent — the explorer — try to solve a new machine learning problem. Give it full access to a validation set and let it experiment and iterate freely, chasing better validation performance over hundreds of rounds. Here the validation set plays the role of the benchmark: a reusable holdout the agent queries again and again. This is the hill-climbing loop that ought to overfit.

Then test how compressible the solution is. A second agent, the compressor, reads the entire transcript of the explorer's work and tries to distill the winning strategy into a very short prompt — just a handful of tokens. That prompt is handed to a third agent, the reproducer, which must implement the strategy from scratch using only the prompt and the training data. Critically, the reproducer has no access to the validation set, the explorer's code, or its transcript. The short prompt is the only channel through which anything learned from the validation set can reach it. (In the study we report in our paper, the compressor and reproducer are both Claude models.)

If the reproducer — starting cold, armed only with a few tokens — matches the explorer's performance, then all the validation-dependent information needed to specify the strategy fit through that tiny channel. The strategy was compressible. We call this a certificate of output compression.

The setup has a very useful property that human research communities lack: the reproducer can be reset over and over. The compressor can try many different compressions and see how well each is decoded, because every attempt lands on a fresh reproducer with no memory of the last one. It is a little like the film Memento — you are leaving a terse note for a version of yourself whose memory will be wiped before reading it. You learn to write notes that a knowledgeable but amnesiac copy of you can act on; those notes can be very short because the receiver will fill in anything you leave unsaid exactly as you would have.
CompressionModels-04-1x1.png
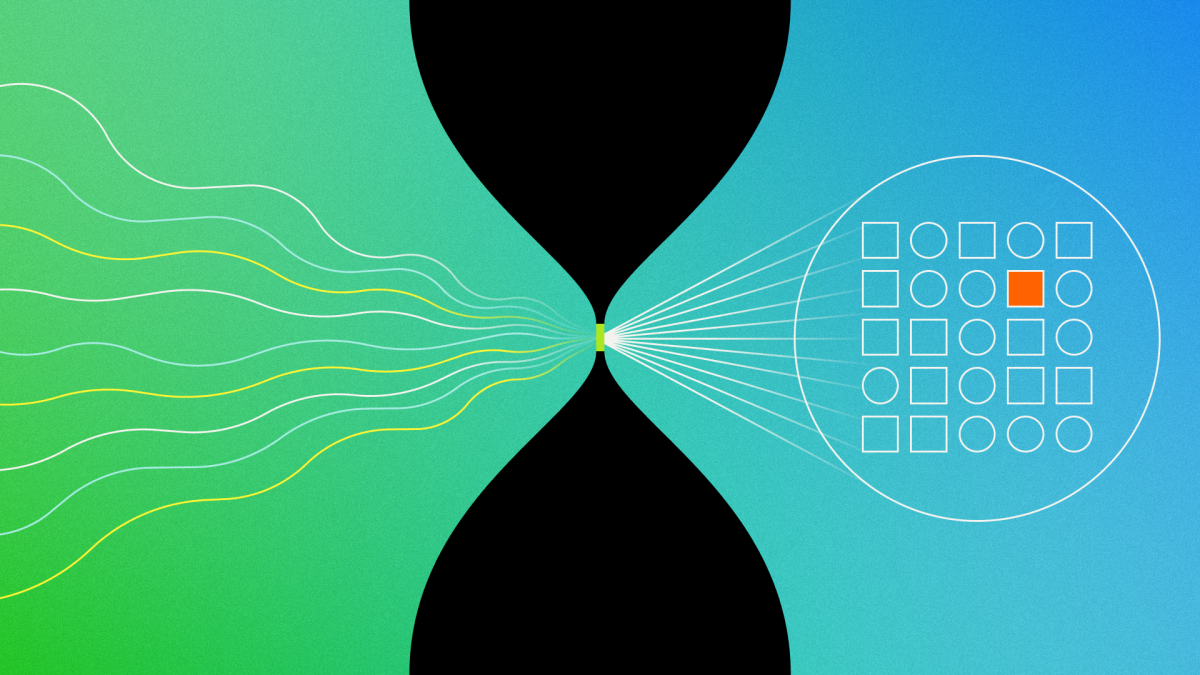
In the researchers' experiments, an explorer agent's strategy is squeezed through a narrow information bottleneck. Whatever survives compression must reflect real structure, not memorized data.

What comes out the other end

The compressions turn out to be remarkably small. Across eight datasets — spanning tabular classification, image classification, language modeling, diffusion modeling, and reward modeling — 32-token prompts were enough for a fresh reproducer to match the explorer's adaptively optimized models on the large majority of problems. One language-modeling strategy survived compression down to just 16 tokens with no loss in held-out performance.

What do these prompts actually look like? The most revealing examples are right at the border of conciseness where the compression almost breaks. In one language-modeling experiment, the explorer discovered a custom GPT-style training recipe. Under a 16-token budget, this was still enough for fresh reproducers to match the uncompressed explorer:

QKn 12L768 Mu .1 R² b2M 4x

To a human reader this looks cryptic, but to another ML agent it says something concrete: QKn means “QK normalization”, 12L768 means a 12-layer, 768-dimensional transformer, Mu .1 means the Muon optimizer with learning rate 0.1, R² means squared-ReLU activations, b2M means a two-million-token batch, and 4x means a fourfold feed-forward block. Cut the budget to eight tokens, however, and the prompt becomes

12L768 Mu .1 R²

Now the reproducer no longer matches the explorer. The missing pieces specified real training choices that were made as a function of the data and differ from the most obvious defaults. This boundary shows the limits of compressibility and is important. It shows that the reproducer is not succeeding from prior knowledge alone. A few compressed tokens are carrying genuine information learned from the data itself, and when those tokens disappear, so does the performance.

We also ran a set of experiments that imposed an information bottleneck from the other direction. Instead of compressing the explorer's output, we compressed its input: rather than telling the explorer each model's numerical validation score, we returned only a single bit — did this model beat the running best, or not? Even reduced to one bit of feedback per query, the explorer found strategies as good as those it found with full numerical scores. The channel between the validation set and the final strategy is narrow in both directions, and the one-bit version even comes with a rigorous mathematical guarantee on generalization.

Across eight datasets, strategies that emerged from hundreds of iterative experiments could be compressed into prompts as short as 16 to 32 tokens — small enough for a fresh agent with no memory to reproduce the original results.

Catching cheaters

A good empirical theory should be falsifiable — and this one is. If low overfitting is really explained by compressibility, then models that genuinely overfit should fail to be compressible via this pipeline.

To check, we deliberately pushed agents into overfitting by handing them direct validation-set access and prompting them to maximize validation performance at any cost. The agents took the bait: in 38 of 102 experimental runs, validation accuracy ran more than 10% ahead of true held-out accuracy.

The theory predicts that these gains should not survive the compression bottleneck, because they encode idiosyncrasies of specific validation examples, not transferable structure. Sure enough, when squeezed through a short prompt to a fresh reproducer, the validation-specific advantages vanished. Compression separated the legitimate strategies from the overfitting ones with very high accuracy.

So compression does not merely explain why autonomous research agents tend not to overfit but offers a tool for catching overfitting when it does occur, by flagging the cases where no short description can reproduce the result.

What this tells us — and what it doesn't

A few caveats are in order. The whole framework assumes that the only path from the validation data to the final model runs through the prompt we feed the reproducer. Of course, if a model had memorized the validation data during pretraining, it would have a side channel that bypasses the information bottleneck we are trying to impose. We don't think that is what is happening in our experiments: agents improve gradually through real search rather than starting at their best, and performance degrades at very short token budgets. But fully resolving this question will likely require experimenting with fresh datasets collected after a model's training cutoff, which we haven’t done.

Most importantly, our results are about LLM agents, because that is where the experiment is possible — where you can reset the subject, control its inputs, and count their length. But the picture they paint is strongly suggestive about human research communities too. When a field spends years climbing a fixed benchmark, and the gains keep transferring to fresh data, it may be for the same reason the agents' strategies survive a 32-token prompt: the recipes that actually work are simple. Or in other words, "What fits (into few tokens) doesn't overfit."

Acknowledgments: Steven Wu

Research areas

Related content

US, WA, Bellevue
The Central Learning Solutions (CLS) Science team in Amazon Operations builds state-of-the-art solutions for enhancing leadership and associate development across the organization. We develop technology and mechanisms for building personalized learning experiences based on the profiles of different learners and assess the post-training performance curves for different learner profiles. As a Data Scientist on the team, you will be driving the data science roadmap for the CLS Science team. You will leverage your knowledge in statistics and econometrics, estimate the causal impact of training interventions, recommend the right interventions for a given learner profile, and measure the post-launch success of these interventions through A/B weblabs. These insights will help in dynamically changing the training content of Learning & Development courses and unlock opportunities to improve both training effectiveness and learner experience. You will collaborate effectively with internal stakeholders and cross-functional teams for solving business problems, create operational efficiencies, and deliver successfully against high organizational standards. Key job responsibilities - Establish scalable, efficient, automated processes for large scale data analyses, model development, model validation and implementation. - Use advanced causal inference methodologies to estimate the learning curves for different learner profiles and the effectiveness of training content. - Perform statistical analysis and statistical tests including hypothesis testing and A/B testing. - Implement new statistical, machine learning, or other mathematical methodologies to solve specific business problems. - Present deep dives and analysis to both technical and non-technical stakeholders, ensure clarity, and influence the strategy of business partners. About the team Central Learning Solutions (CLS) is the centralized technical team that builds Learning & Development products for North America Operations employees. CLS Science teams owns the science components that power the different products on Impact Estimation, Self Serve Analytics, Content Understanding, and Personal learning.
IT, Turin
We're building systems that turn research into real world impact. We're advancing the intelligence behind how customers converse, connect and interact with Alexa across the globe and we're tackling complex conversational AI challenges with state of the art GenAI systems. We're looking for PhD students across multiple research domains to invent, design, and implement state of the art solutions for never before solved problems. Your work here won't just stay in a notebook, it ships to production and reaches customers worldwide. Check out the details below including the job responsibilities, team details, and basic qualifications before submitting your application. You can find more information about the Amazon Science community as well as interview preparation tips via the links below; - https://www.amazon.science/ - https://amazon.jobs/content/en/career-programs/university/science - https://amazon.jobs/content/en/how-we-hire/university-roles/applied-science Key job responsibilities As an Applied Science Intern, you will own the design and development of end-to-end systems. You'll have the opportunity to write technical white papers, create roadmaps and drive production level projects that will support Amazon Science. You will work closely with Amazon scientists and other science interns to develop solutions and deploy them into production. You will have the opportunity to design new algorithms, models, or other technical solutions whilst experiencing Amazon's customer focused culture. The ideal intern should have the ability to work with diverse groups of people and cross-functional teams to solve complex business problems. A day in the life You'll spend your first weeks scoping your project with your mentor, then own the research and implementation end-to-end. Projects may include developing and implementing real-time AI services, conducting comprehensive analysis of GenAI algorithms and methodologies or contributing to the creation of reliable, efficient code for production systems that serve millions of users — depending on the team you're matched with. Many interns publish at top-tier conferences or see their work deployed to production before the internship ends. Interns may also be considered for a return offer at the end of their internship, subject to performance evaluation and headcount availability. Further benefits of an Amazon Science internship include; - All of our internships offer a competitive salary - Interns are paired with an experienced manager and mentor(s) - Interns get invited to different intern program or office events - Interns can build their professional and personal network with other Amazon Scientists - Interns can potentially publish work at top tier conferences About the team You'll submit a single application and we'll match you with science teams best aligned with your research interests. Applications are reviewed on a rolling basis, and your application stays active until we find a team match or confirm there are no matches available. Start dates are available throughout the year for durations of between 3–6 months. Please note, each team has different start date and duration preferences — your recruiter will confirm the preferences of the team you're matched with prior to interviewing. We offer science internships in multiple locations across the EMEA region and you can indicate your interest in all these locations by applying here (Austria, Estonia, France, Germany, Ireland, Israel, Italy, Jordan, Luxembourg, Netherlands, Poland, Romania, South Africa, Spain, Sweden, UAE, and UK). Please note we do not offer remote internships.
US, NY, New York
We are seeking an Applied Scientist to lead the development of evaluation frameworks and data collection protocols for robotic capabilities. In this role, you will focus on designing how we measure, stress-test, and improve robot behavior across a wide range of real-world tasks. Your work will play a critical role in shaping how policies are validated and how high-quality datasets are generated to accelerate system performance. You will operate at the intersection of robotics, machine learning, and human-in-the-loop systems, building the infrastructure and methodologies that connect teleoperation, evaluation, and learning. This includes developing evaluation policies, defining task structures, and contributing to operator-facing interfaces that enable scalable and reliable data collection. The ideal candidate is highly experimental, systems-oriented, and comfortable working across software, robotics, and data pipelines, with a strong focus on turning ambiguous capability goals into measurable and actionable evaluation systems. Key job responsibilities - Design and implement evaluation frameworks to measure robot capabilities across structured tasks, edge cases, and real-world scenarios - Develop task definitions, success criteria, and benchmarking methodologies that enable consistent and reproducible evaluation of policies - Create and refine data collection protocols that generate high-quality, task-relevant datasets aligned with model development needs - Build and iterate on teleoperation workflows and operator interfaces to support efficient, reliable, and scalable data collection - Analyze evaluation results and collected data to identify performance gaps, failure modes, and opportunities for targeted data collection - Collaborate with engineering teams to integrate evaluation tooling, logging systems, and data pipelines into the broader robotics stack - Stay current with advances in robotics, evaluation methodologies, and human-in-the-loop learning to continuously improve internal approaches - Lead technical projects from conception through production deployment - Mentor junior scientists and engineers About the team Fauna Robotics, an Amazon company, is building capable, safe, and genuinely delightful robots for everyday life. Our goal is simple: make robots people actually want to live and interact with in everyday human spaces. We believe that future won’t arrive until building for robotics becomes far more accessible. Today, too much effort is spent reinventing the fundamentals. We’re changing that by developing tightly integrated hardware and software systems that make it faster, safer, and more intuitive to create real-world robotic products. Our work spans the full stack: mechanical design, control systems, dynamic modeling, and intelligent software. The focus is not just functionality, but experience. We’re building robots that feel responsive, expressive, and genuinely useful. At Fauna, you’ll work at the frontier of this space, helping define how robots move, manipulate, and interact with people in natural environments. It’s an opportunity to solve hard problems across hardware and software with a team focused on making robotics accessible and joyful to build. If you care about making robotics real for everyone and building systems that are as delightful as they are capable, we’re interested in hearing from you.
US, WA, Bellevue
Amazon Global Fleet and Products (GFP) organization is responsible for fleet programs and capacity. The Fleet Planning team is looking for a Data Scientist to drive the most efficient use of fleet. Amazon Middle and Last Mile fleet planning is a complex resource allocation problem. The goal of fleet allocation planning is to optimize the size and mix of fleet allocated to various programs through. Changes in routes, network, exiting DSPs and new DSP onboarding create continuous need for re-allocation of fleet to maintain an efficient network capacity. This requires allocation to adhere to various operational limits (repair network, EV range, Station Charging capability) and also match route’s cube need to vehicles capacity. As a Data Scientist on the Fleet Planning team (GFP), you will be responsible for building new science models (linear programs, statistical and ML models) and enhancing existing models for changing business needs. You would work with program managers in planning, procurement, redeployment, deployment, remarketing, variable fleet and infrastructure programs to build models that would support the requirements of all programs in a coherent plan. Key job responsibilities • Build models and automation for planners for generating vehicle allocation plans • Partner with program teams to test and measure success of implemented model • Lead reviews with senior leadership, deep dive model outputs and explain implications of model recommendations.
IN, KA, Bangalore
Are you passionate about solving complex logistics challenges? Our Analytics team is at the forefront of enhancing delivery experiences through data-driven solutions and innovative technology. As a Research Scientist, you will join a team dedicated to optimizing our delivery network, ensuring reliable and efficient service to our customers. We are seeking an enthusiastic, customer-centric professional with strong analytical capabilities to drive impactful projects, implement advanced solutions, and develop scalable processes. In this role, you will have immediate ownership of business-critical challenges and the opportunity to make strategic, data-driven decisions that shape the future of our delivery operations. Your work will directly influence customer experience and operational excellence. The ideal candidate will possess both research science capabilities and program management skills, thriving in an environment that requires independent decision-making and comfort with ambiguity. This role offers the opportunity to make a significant impact on our advanced logistics network while working with pioneering technology and data science applications. Basic qualifications • 3+ years of building machine learning models for business application experience • Knowledge of programming languages such as C/C++, Python, Java or Perl • Experience programming in Java, C++, Python or related language • Experience with neural deep learning methods and machine learning Preferred qualifications: • PhD in engineering, technology, computer science, machine learning, robotics, operations research, statistics, mathematics or equivalent quantitative field • 5+ years of extensive relevant research experience • Deep expertise in Machine Learning • Proficiency in programming • Core competency in mathematics and statistics • Track record of successful projects in algorithm design and product development • Publications at peer-reviewed conferences or journals • Strategic thinker with good execution skills • Exhibits excellent business judgment • Effective verbal and written communication skills • Experience working with real-world data sets and building scalable models from big data • Experience with modern modeling tools and frameworks such as R, scikit-learn, Spark MLLib, MxNet, Tensorflow • Experience with large scale distributed systems
IN, KA, Bengaluru
We are looking for Applied Scientists to advance how Minerva detects and responds to risk across KDP and Kindle Unlimited, building new models and raising the bar on the ones in production. You will own a problem end to end, from framing and modeling through evaluation and production launch, working with scientists and engineers in Bengaluru and the US. Key job responsibilities - Monitor production risk models and push their quality higher: track performance and drift, improve how performance is measured, and lead the deep-dive science that turns model behavior into better detection. - Design, train, and evaluate improved detection models, and take them to production with engineering partners. - Build datasets, labels, evaluation sets, and metrics, and strengthen them as abuse patterns change. - Write clear readouts with recommendations for scientists, engineers, and policy partners. About the team Kindle Direct Publishing (KDP) has empowered a new wave of self-motivated creators, tearing down barriers that once blocked writers from reaching readers. Minerva is the science and analytics organization for Amazon's Books business. We build systems for content understanding, author marketing and discovery, fraud and abuse prevention, and content risk, and we optimize manufacturing, fulfillment, and quality for Print On Demand (POD). We have mature areas and green-field opportunities, with engineering, business intelligence, and data engineering support across our areas. We are now building science teams in Bengaluru that work closely with our scientists in the US. Risk Science, a team within Minerva, keeps fraud, abuse, copyright infringement, and harmful content out of the Books catalog and programs such as Kindle Unlimited, using text, image, and behavioral data.
US, NY, New York
We are seeking a Robotics/AI Motor Control Scientist to develop cutting-edge machine learning algorithms for motor control systems in robots. In this role, you will focus on creating and optimizing intelligent motor control strategies to enable robots to perform complex, whole-body tasks. Your contributions will be essential in advancing robotics by enabling fluid, reliable, and safe interactions between robots and their environments. Key job responsibilities - Develop controllers that leverage reinforcement learning, imitation learning, or other advanced AI techniques to achieve natural, robust, and adaptive motor behaviors - Collaborate with multi-disciplinary teams to integrate motor control systems with robotic hardware, ensuring alignment with real-world constraints such as actuator dynamics and energy efficiency - Use simulation and real-world testing to refine and validate control algorithms - Stay updated on advancements in robotics, AI, and control systems to apply advanced techniques to robotic motion challenges - Lead technical projects from conception through production deployment - Mentor junior scientists and engineers - Bridge research initiatives with practical engineering implementation About the team Fauna Robotics, an Amazon company, is building capable, safe, and genuinely delightful robots for everyday life. Our goal is simple: make robots people actually want to live and interact with in everyday human spaces. We believe that future won’t arrive until building for robotics becomes far more accessible. Today, too much effort is spent reinventing the fundamentals. We’re changing that by developing tightly integrated hardware and software systems that make it faster, safer, and more intuitive to create real-world robotic products. Our work spans the full stack: mechanical design, control systems, dynamic modeling, and intelligent software. The focus is not just functionality, but experience. We’re building robots that feel responsive, expressive, and genuinely useful. At Fauna, you’ll work at the frontier of this space, helping define how robots move, manipulate, and interact with people in natural environments. It’s an opportunity to solve hard problems across hardware and software with a team focused on making robotics accessible and joyful to build. If you care about making robotics real for everyone and building systems that are as delightful as they are capable, we’re interested in hearing from you. an opportunity to solve hard problems across hardware and software with a team focused on making robotics accessible and joyful to build. If you care about making robotics real for everyone and building systems that are as delightful as they are capable, we’re interested in hearing from you.
US, CA, Pasadena
We are seeking Applied and Research Scientists to join the Safe Autonomy Frontiers (SAF) Lab. In this role, you will develop and deploy the science of safe autonomy on highly dynamic robots, advancing the frontier through both foundational research and realization on hardware. You will contribute to achieving safe autonomy across three key areas: control barrier function (CBF) theory for robust and performant safety on hardware; safe reinforcement learning for agile whole-body control; and layered safety filters that interface with learning, perception, and semantic reasoning systems. You will validate your work experimentally on state-of-the-art robotic platforms — removing bottlenecks to deployment and enabling robots to safely operate around humans. You will work with the inventor of CBFs, as well as top scientists and engineers at Amazon developing the next generation of safe autonomy. Key job responsibilities -Advance the science of safe autonomy from formal foundations to the integration with learning and perception to validation on hardware — with particular emphasis on methods that bridge these domains. -Test and validate hardware, with a focus on next generation robotic systems. Including locomotion, manipulation and loco-manipulation. -Leverage the deployments on hardware to validate the underlying science, identifying gaps between theory and practice that drive the next cycle of research. hardware to validate the underlying science, identifying gaps between theory and practice that drive the next cycle of research. -Publish research at top-tier robotics, control, and ML venues, and contribute to Amazon’s scientific reputation in advanced robotics. -Collaborate with SAF Lab and Amazon production teams to move research into robots deployed at Amazon scale. A day in the life Amazon offers a full range of benefits that support you and eligible family members, including domestic partners and their children. Benefits can vary by location, the number of regularly scheduled hours you work, length of employment, and job status such as seasonal or temporary employment. The benefits that generally apply to regular, full-time employees include: -Medical, Dental, and Vision Coverage -Maternity and Parental Leave Options -Paid Time Off (PTO) -401(k) Plan If you are not sure that every qualification on the list above describes you exactly, we’d still love to hear from you! At Amazon, we value people with unique backgrounds, experiences, and skillsets. If you’re passionate about this role and want to make an impact on a global scale, please apply! About the team The Safe Autonomy Frontiers (SAF) Lab is the first industry research lab dedicated to safe autonomy, founded by the inventor of control barrier functions. We are developing a universal safety layer for the next generation of robotic systems: mobile robots, manipulators, quadrupeds, and humanoids. Here you will advance performant safety for highly dynamic robots — CBF theory integrated with perception and learning, evaluated on next-generation platforms — and your work will underpin robots operating alongside people at Amazon’s unprecedented scale.
RO, Bucharest
We're building systems that turn research into real-world impact — developing AI-driven detection systems that identify and remediate security access violations across Amazon's global operations, and building ML solutions that leverage product images, text, and tabular data to improve safety and compliance mechanisms across Amazon's entire product catalog. If this sounds interesting to you then we have a range of opportunities for you to explore. We're looking for PhD students across multiple research domains to invent, design, and implement state-of-the-art solutions for never-before-solved problems. Your work here won't just stay in a notebook — it ships to production and reaches customers worldwide. Check out the details below including the job responsibilities, team details, and basic qualifications before submitting your application. You can find more information about the Amazon Science community as well as interview preparation tips via the links below; - https://www.amazon.science/ - https://amazon.jobs/content/en/career-programs/university/science - https://amazon.jobs/content/en/how-we-hire/university-roles/applied-science Key job responsibilities As an Applied Science Intern, you will own the design and development of end-to-end systems. You'll have the opportunity to write technical white papers, create roadmaps and drive production level projects that will support Amazon Science. You will work closely with Amazon scientists and other science interns to develop solutions and deploy them into production. You will have the opportunity to design new algorithms, models, or other technical solutions whilst experiencing Amazon's customer focused culture. The ideal intern should have the ability to work with diverse groups of people and cross-functional teams to solve complex business problems. A day in the life You'll spend your first weeks scoping your project with your mentor, then own the research and implementation end-to-end. Your work could involve building graph-based ML models and knowledge graphs that detect and remediate access violations at global scale, developing behavioral pattern clustering and automated reasoning systems for security operations, or researching multimodal and computer vision approaches on product catalog data to improve safety and compliance mechanisms — depending on the team you're matched with. Many interns publish at top-tier conferences or see their work deployed to production before the internship ends. Interns may also be considered for a return offer at the end of their internship, subject to performance evaluation and headcount availability. Further benefits of an Amazon Science internship include; - All of our internships offer a competitive salary - Interns are paired with an experienced manager and mentor(s) - Interns get invited to different intern program or office events - Interns can build their professional and personal network with other Amazon Scientists - Interns can potentially publish work at top tier conferences About the team We generally hire interns for multiple teams in Romania, including but not limited to; • CoSS — Research and develop ML solutions that improve safety and compliance across Amazon's entire product catalog working with tabular, textual, and product image data using deep learning, computer vision, LLMs, and multimodal models • Monitored Access Detection — Build AI-driven detection and remediation systems that identify global access violations across Amazon — leveraging knowledge graphs, graph modeling, behavioral pattern clustering, generative AI, and reinforcement learning to create a self-improving, closed-loop security system. You'll submit a single application and we'll match you with science teams best aligned with your research interests. Applications are reviewed on a rolling basis, and your application stays active until we find a team match or confirm there are no matches available. Start dates are available throughout the year for durations of between 3–6 months. Please note, each team has different start date and duration preferences — your recruiter will confirm the preferences of the team you're matched with prior to interviewing. We offer science internships in multiple locations across the EMEA region and you can indicate your interest in all these locations by applying here (Austria, Estonia, France, Germany, Ireland, Israel, Italy, Jordan, Luxembourg, Netherlands, Poland, Romania, South Africa, Spain, Sweden, UAE, and UK). Please note we do not offer remote internships.
IL, Tel Aviv
We're building systems that turn research into real-world impact — powering sports experiences for millions of Prime Video customers, pioneering multimodal document intelligence, building autonomous AI agents that reason, plan, and act, and transforming how customers discover products they love. If this sounds interesting to you then we have a range of opportunities for you to explore. We're looking for Masters students across multiple research domains to invent, design, and implement state-of-the-art solutions for never-before-solved problems. Your work here won't just stay in a notebook — it ships to production and reaches customers worldwide. Check out the details below including the job responsibilities, team details, and basic qualifications before submitting your application. You can find more information about the Amazon Science community as well as interview preparation tips via the links below; - https://www.amazon.science/ - https://amazon.jobs/content/en/career-programs/university/science - https://amazon.jobs/content/en/how-we-hire/university-roles/applied-science Key job responsibilities As an Applied Science Intern, you will own the design and development of end-to-end systems. You'll have the opportunity to write technical white papers, create roadmaps and drive production level projects that will support Amazon Science. You will work closely with Amazon scientists and other science interns to develop solutions and deploy them into production. You will have the opportunity to design new algorithms, models, or other technical solutions whilst experiencing Amazon's customer focused culture. The ideal intern should have the ability to work with diverse groups of people and cross-functional teams to solve complex business problems. A day in the life You'll spend your first weeks scoping your project with your mentor, then own the research and implementation end-to-end. Your work could involve building computer vision models that power live sports experiences for Prime Video, developing multimodal GenAI solutions for AWS document intelligence, creating agentic AI systems that reason and act autonomously, or advancing recommendation models that transform how customers discover content — depending on the team you're matched with. Many interns publish at top-tier conferences or see their work deployed to production before the internship ends. Interns may also be considered for a return offer at the end of their internship, subject to performance evaluation and headcount availability. Further benefits of an Amazon Science internship include; - All of our internships offer a competitive salary - Interns are paired with an experienced manager and mentor(s) - Interns get invited to different intern program or office events - Interns can build their professional and personal network with other Amazon Scientists About the team We're hiring interns for multiple teams in Israel, including but not limited to; • Prime Video Sports — Build innovative sports experiences for Prime Video, spanning computer vision, 3D simulation, and personalized content recommendations. • Personalization — Leverage LLMs, NLP, and recommender systems to match customers with products that align with their passions and shopping preferences. • Agentic AI — Build next-generation agentic AI systems that automate real-world knowledge work, spanning retrieval-augmented generation, multi-agent workflows, long-term memory and personalization, knowledge-graph construction, and agent evaluation. • DS3 Textract — Develop multimodal generative AI algorithms that pioneer state-of-the-art document understanding solutions impacting millions of customers. You'll submit a single application and we'll match you with science teams best aligned with your research interests. Applications are reviewed on a rolling basis, and your application stays active until we find a team match or confirm there are no matches available. Start dates are available throughout the year. Some teams offer full-time internships (3–6 months) while others offer part-time positions (50–60%, 8–12 months) — your recruiter will confirm the format during team matching. We offer science internships in multiple locations across the EMEA region and you can indicate your interest in all these locations by applying here (Austria, Estonia, France, Germany, Ireland, Israel, Italy, Jordan, Luxembourg, Netherlands, Poland, Romania, South Africa, Spain, Sweden, UAE, and UK). Please note we do not offer remote internships.